“Find me a private tour that works with my cruise stop.”
It looks like one search query. But a useful answer depends on several decisions.
Which port? What time can the traveller leave the ship? When must they return? How far away does the tour start? Is transport included? Does the experience suit everyone in the party?
For a travel marketplace, this is what makes query fan-out worth understanding.
The opportunity goes beyond finding more variations of “private shore excursion.” It involves understanding which questions must be resolved before someone can confidently choose an experience.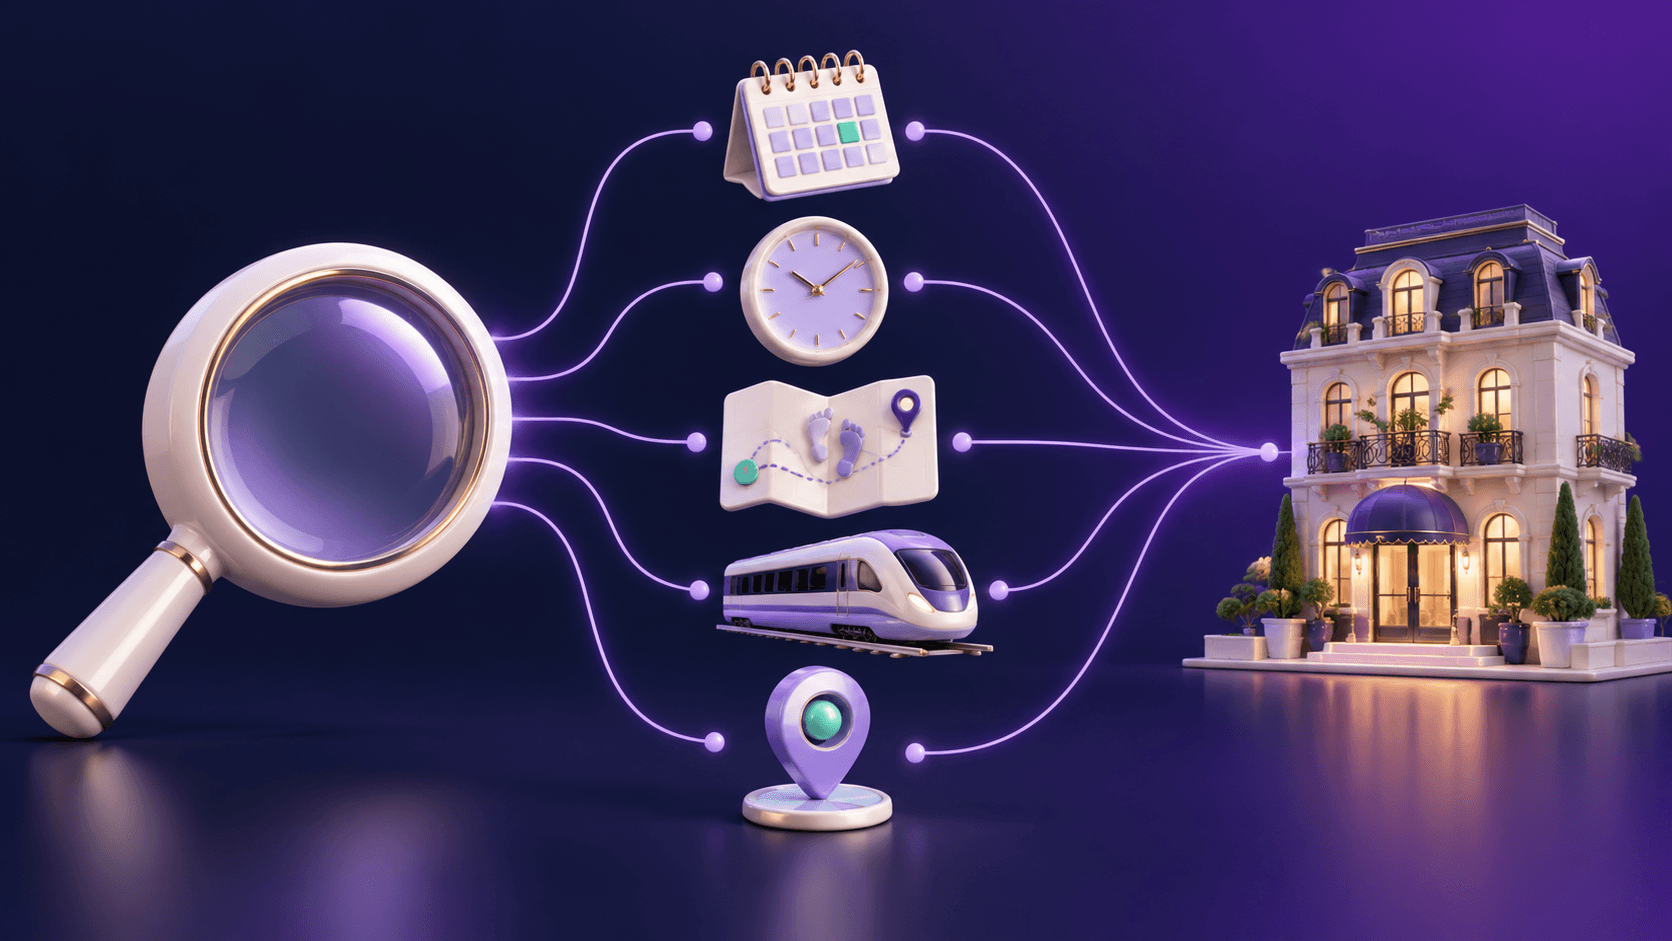
What we know—and what we are modelling
Google explains that AI Overviews and AI Mode may use query fan-out: issuing related searches across subtopics and data sources to develop a response. It also notes that the two experiences may use different models and techniques, producing different answers and links. Google’s AI search documentation.
That establishes the broad behavior. It does not reveal the exact searches generated for every request.
When I create a fan-out map, I would treat it as a model of the information need. Unless a platform exposes its searches, I would not claim that my map reconstructs its internal process.
That distinction matters when turning research into an SEO recommendation.
A better query and several related queries solve different problems
Olaf Kopp’s research connects query fan-out with earlier work on query refinement, expansion, and augmentation. That historical perspective is useful: search systems were processing and reformulating questions long before conversational interfaces became familiar. Kopp’s query-processing article.
For practical planning, I would distinguish the jobs like this:
| Job | Illustrative travel example |
|---|---|
| Clarify an ambiguous request | Establish which “Victoria” the traveller means |
| Broaden retrieval vocabulary | Consider “shore excursion” alongside “cruise day trip” |
| Add relevant context | Include the port and the traveller’s available hours |
| Investigate separate requirements | Check meeting arrangements, walking demands, and return timing |
These are working distinctions, not a universal sequence followed by every search system.
The important point is that rewriting a phrase and investigating several requirements are different tasks. A content plan needs to account for both.
Start with the decision, then identify the missing evidence
Imagine a hypothetical traveller asking:
We have one day in port, two children, and a grandparent who cannot manage many stairs. Which private tour should we choose?
I would first separate what the traveller has told us from what remains unknown.
We know the party includes children and someone with a mobility constraint. We do not yet know the port, the children’s ages, the available time, or what “many stairs” means for this person.
Some gaps require clarification from the traveller. Searching more extensively cannot reliably resolve them.
Once those details are known, I would map the evidence needed to evaluate an offer:
| Decision | Evidence needed |
|---|---|
| Can the group reach the start? | Exact meeting point and transport arrangements |
| Is the route suitable? | Steps, surfaces, walking distance, and breaks |
| Does the timing work? | Departure, duration, return location, and relevant buffers |
| Can the whole party participate? | Age restrictions and group-capacity rules |
| What happens if plans change? | Applicable cancellation and delay conditions |
This is a content-gap analysis with a specific purpose: finding what prevents a sound recommendation.
Some questions depend on earlier answers
A flat list can hide the order in which information becomes useful.
Before comparing transfer times, we need the actual arrival point. Before judging whether the return is suitable, we need the traveller’s required boarding time. Before checking availability, we need a date and party configuration.
I would therefore map dependencies as well as topics.
A simple planning sequence might be:
Arrival details → usable time → feasible experiences → suitable departure → current offer
That is an illustrative workflow, not a claim about a particular AI system’s architecture.
It helps the content team identify why a page can appear comprehensive while still being difficult to use. The information may exist, but the reader cannot connect it to the conditions that matter.
Generated questions are hypotheses, not demand data
An LLM can help generate questions a team has overlooked.
I would use that capability to challenge an initial map: what could make this tour unsuitable? Which requirement remains unanswered? What information would distinguish two similar offers?
But a generated question does not establish that people search for it frequently. It also does not prove that Google issues that query internally.
I would compare suggestions with available evidence: customer enquiries, on-site searches, Search Console queries, supplier questions, and booking-support themes.
Each source has limits. Search Console shows queries associated with the site’s search performance; it is not a complete record of hidden fan-out searches.
The generated map is a starting point for investigation.
Avoid creating a page for every branch
Suppose the exercise produces thirty useful questions.
That does not mean we need thirty articles.
The meeting point belongs on the relevant listing. General advice about planning a cruise day may belong in an editorial guide. A supplier’s cancellation conditions belong with the applicable offer.
I would assign each question to the page or system best placed to answer it accurately.
A useful content map should record:
- The customer question.
- The source qualified to answer it.
- The page or interface where the answer belongs.
- The conditions that might change it.
- The owner responsible for maintenance.
This prevents a fan-out exercise from becoming a production quota.
Keep the qualification beside the answer
A passage can be relevant and still misleading when separated from its context.
“Pickup is included” leaves important questions open. Included for which departure, from which area, and under which option?
I would write the relevant conditions close to the claim. Where the details depend on the booking, I would direct the traveller to the specific offer rather than make a general promise.
This improves the usefulness of the passage whether it is read on the page, quoted elsewhere, or summarized by a system.
It does not require writing every section as a miniature FAQ. It requires keeping the meaning intact.
Test whether the content supports a decision
Before measuring citations, I would test answerability.
Give a reviewer the hypothetical booking request and the relevant pages. Ask them to identify a suitable option and explain the evidence behind the choice.
Where must they guess? Which statements conflict? Which unknowns require a question to the traveller or supplier?
Those gaps provide a concrete editing backlog.
AI answer checks can then become a separate observation exercise: record the prompt, platform, date, cited sources, and factual accuracy. An appearance in one answer does not prove that a particular content change caused it.
What I would take into the next audit
I would choose one complex booking request and follow it through the marketplace.
The result I want is a clear account of the decisions involved, the evidence supporting them, and the unanswered questions that could change the recommendation.
That makes query fan-out useful beyond the terminology.
It gives me a way to ask whether our content helps someone complete the reasoning behind a booking—or simply contains the words associated with it.