A brand can appear when an assistant is asked to name Canadian companies and disappear when the question describes what someone actually needs.
That was one of the most useful observations from my AI Shelf research. The same category can produce different shortlists depending on whether the question asks for an identity, a product type or a specific use case.
In my skincare sample, several Canadian independent brands appeared in answers to the Canadian-brand question but not in the sampled questions about skin needs. In the apparel study, the two assistants often returned different sets of brands even when the question was identical.
Those findings made me reconsider what I would put in an AI visibility report. A total mention count can make a business look visible while hiding the decisions for which it is absent. It can also combine a passing example, a linked brand and an actual recommendation as though they mean the same thing.
I wanted to understand the shape of that gap before proposing more content.
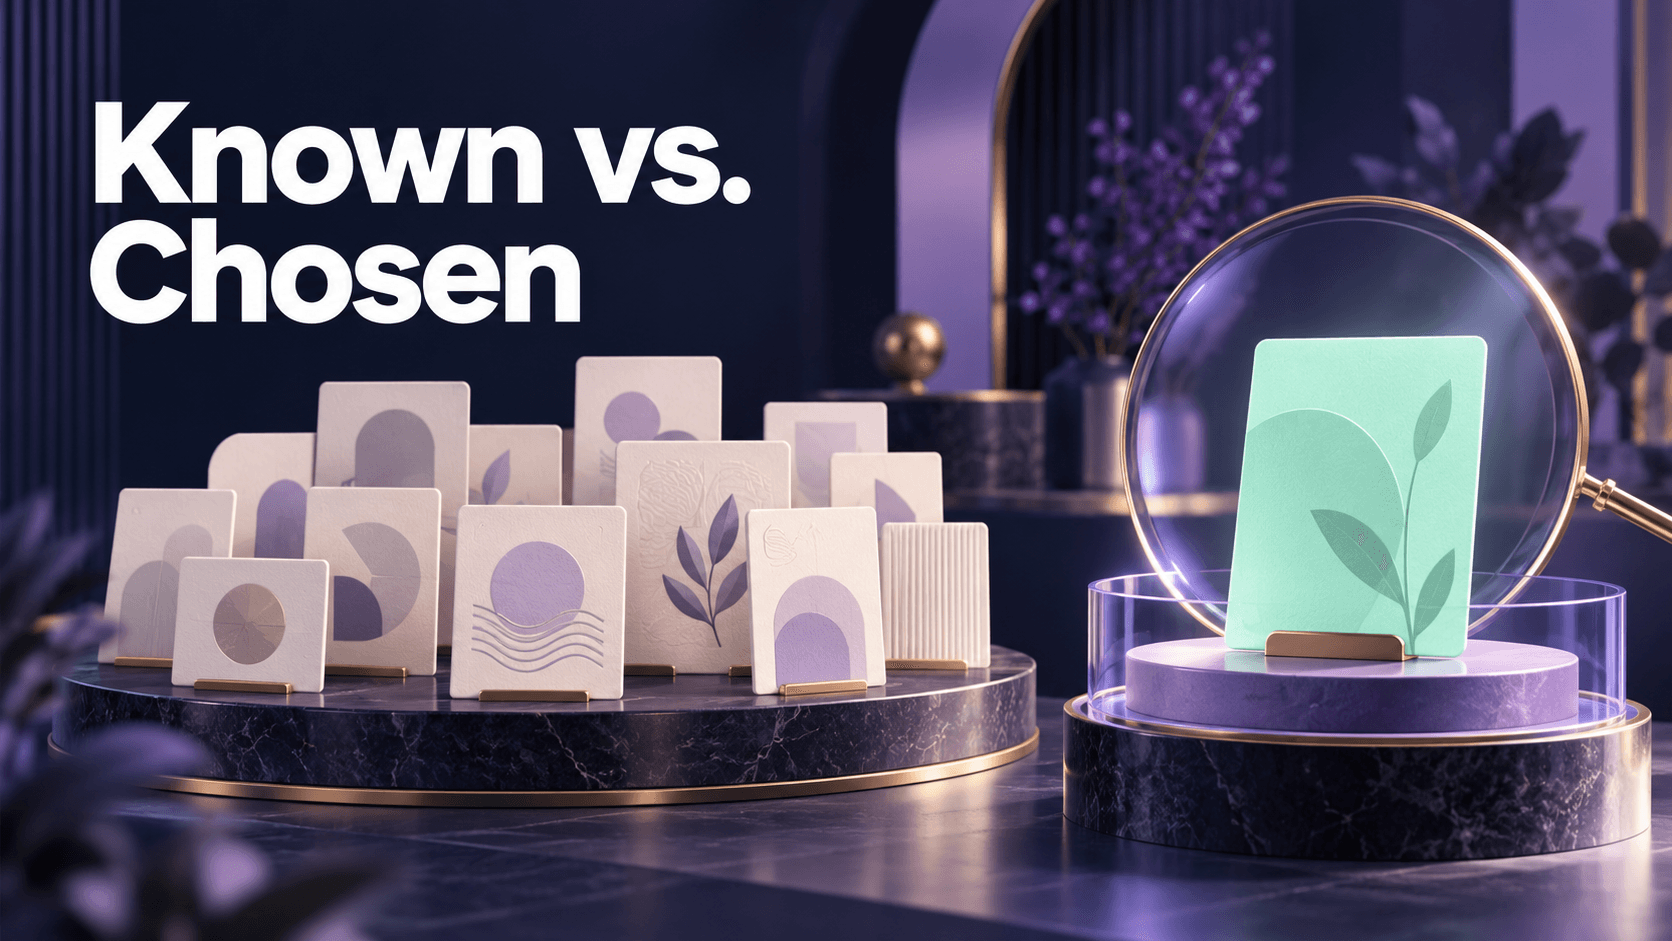
Conceptual illustration of the difference between appearing in a category and being selected for a need. The cards do not represent measured rankings.
Two studies, two different categories
The first AI Shelf study examined sustainable apparel. I asked 12 questions in ChatGPT and Google AI Mode on October 22, 2026, producing 24 answers. Four questions covered awareness, four consideration and four decision-stage brand checks.
Eight questions did not name a brand. Across two systems, those created 16 unbranded answers. That is the denominator for findings such as tentree appearing in eight of 16 answers.
The second AI Shelf study examined skincare. It used nine questions across the same broad journey stages on October 24, producing 18 answers. Six prompts were unbranded, creating 12 unbranded answers across the two systems.
I collected both studies from Vancouver. ChatGPT used temporary chats; Google AI Mode ran signed in. The reports recorded brands, visible links and recurring descriptive language. The apparel matching could identify a brand through a link as well as through answer text, an important qualification when interpreting “appearance.”
These were dated snapshots of public answers. I did not have the brands’ analytics, test their products or measure purchases. I was studying representation in the answer, not validating the recommendations themselves.
The Canadian-brand list was a different opportunity
In skincare, the prompt asking for Canadian brands surfaced names including Three Ships, Graydon and Province Apothecary. In the sampled questions framed around skin needs, those brands did not appear.
The Ordinary crossed between those contexts. Across all 12 unbranded answers, it appeared five times, while CeraVe appeared six times.
That does not prove why either brand was selected. It does show why I would separate a country-of-origin association from a customer-need association in the measurement.
“Name Canadian skincare brands” asks for membership in a category. “Which affordable fragrance-free brands are sold in Canada?” adds a set of constraints. A brand can be correctly recognized as Canadian without the answer demonstrating that it is suitable for the second request.
I would not solve that gap by attaching a long list of needs to every product page. Any suitability claim must be supported by the product’s actual properties and appropriate evidence. This article reports language in AI answers; it does not evaluate skincare efficacy or provide a product recommendation.
The strategic question is whether the business can substantiate the association it wants to earn. If it cannot, the right response may be a narrower positioning claim rather than more assertive copy.
Even the same question did not produce the same shelf
In the apparel study, only three of the eight unbranded prompt pairs shared any brand between ChatGPT and Google AI Mode. For the question about affordable ethical brands shipping within Canada, the recorded brand sets had no overlap.
That is a useful contrast, but it needs careful wording. Some questions were educational and did not necessarily require naming a brand. An absence of overlap is not always a disagreement about which company is best; one answer may simply have offered advice without examples.
Nor does this sample establish stable differences between the platforms. Each question was observed once in each system on one date, under different account conditions.
What it establishes for my reporting is simpler: checking one assistant once would have missed part of the observed picture. The platform, prompt and stage belong beside the mention count.
I would also preserve the answer itself. A summary spreadsheet cannot show whether the brand was a strong recommendation, a qualified option or a reference in a comparison unless someone records that distinction.
A mention, a recommendation and a source are separate observations
The AI Shelf metaphor is helpful because it makes selection visible. But I do not want the metaphor to conceal different forms of presence.
A brand may be named in a general explanation. Its website may appear as a source for a fact. A product may be shown as an option. An answer may recommend a competing product while citing the brand for a specification.
Each is worth recording. None should automatically inherit the meaning of the others.
For a repeat study, I would code at least three things separately: whether the brand is present, whether it is recommended for the request, and whether a brand-owned page is visibly linked. I would add the stated reason and any limitation attached to the recommendation.
That would make the findings more actionable. A business absent from a relevant shortlist faces a different problem from one that appears for the wrong use case. A website cited for evidence faces a different opportunity from a product recommended without a link.
My existing article on the accuracy of brand recommendations explains the audit logic. These studies supply specific examples of why the distinctions matter.
The language around a category also changed
The apparel answers mentioned recycled materials in 20 of 24 answers. In skincare, named ingredients appeared in 13 of 18 answers.
Those counts describe recurring language, not verified quality or causal selection criteria. An ingredient name appearing in an answer does not prove efficacy. A sustainability term appearing does not establish the environmental performance of a product.
Still, the comparison gives me a useful starting point for a content review. Different categories bring different questions about evidence. A generic brand story cannot resolve every product-level uncertainty.
For apparel, I might inspect whether a material claim identifies the product, the relevant component and the evidence behind it. For a skincare business, I would involve qualified reviewers when interpreting or communicating health-adjacent claims. The analysis should respect the limits of the marketer’s expertise.
The broader lesson is to research what customers need to verify within a category, then check whether the business provides that evidence clearly. Repeating the vocabulary found in an AI answer is not a substitute for supplying the underlying facts.
More links did not automatically mean better evidence
The apparel report counted 26 distinct source links in ChatGPT and 91 in Google AI Mode. Twenty-four of ChatGPT’s links pointed to brand-owned sites. The Google sample included a wider mix of brand, editorial, community and ratings sources.
In the skincare study, ChatGPT showed sources in two of nine answers; Google AI Mode showed sources in all nine.
I would not use those observations to declare one system more trustworthy. A link count does not tell me whether each source supports its associated claim, whether the source is current or whether the recommendation is appropriate.
It does suggest that a visibility review should inspect the evidence environment around the answer. Who is being cited? For which statement? Does the supporting material describe the product being recommended, or only the company generally?
Those questions can lead to a better brief for owned content or a more focused review of external descriptions. They do not support a promise that a particular placement or certification will cause an AI recommendation.
How I would turn the findings into a useful audit
I would start with the decisions a business wants to support, rather than a large list of prompts containing its name.
First, I would define discovery questions: category, location and operating model. Then I would add need-based questions involving genuine requirements. Finally, I would test brand-specific comparisons and situations in which the business should not be selected.
For every prompt, I would record the platform, date, account context, full answer and visible sources. Repeated runs would help distinguish a recurring association from a single appearance. My repeated-search experiment shows why one observation should not carry the entire conclusion.
The next step would be an evidence review. For each desired association, can the business supply current facts supporting it? Which page explains them? Who can verify the claim? Does an external source describe the same scope?
A missing association without supporting evidence is not yet a content gap. It may be a product limitation, an unsupported positioning ambition or a question the business should not try to own.
A travel application: destination visibility versus booking fit
The following is a proposed application of the research, not a measured travel result.
A tour business might appear for “private tours in Barcelona” but be absent when the request adds a cruise schedule, limited walking or a family’s age range. A hotel might be recognized in a neighbourhood list while lacking the evidence needed for a room-occupancy or cancellation question.
I would separate destination recognition from eligibility for the specific request. Then I would examine the facts that determine fit: start and end times, meeting arrangements, physical demands, room configuration, conditions and availability.
Those details cannot all be established by a destination guide. Some belong on listings; some require operational confirmation or live booking data. A content strategy has to recognize that boundary.
If an answer overgeneralizes a capability, I would correct the source material where possible and record the mismatch. If it excludes the business appropriately, I would not count that as a failure simply because a visibility score went down.
The aim is an accurate match between the request and what can actually be booked.
What I would avoid claiming from this research
These studies do not show that certifications, ingredient names, external reviews or particular words caused a brand to appear. They do not measure overall market share, preference among real shoppers or sales influence.
The prompt sets differed across categories and were collected on different dates. I would not pool the answers into one grand “AI recommendation rate.” Their value lies in the comparisons within a documented setup and the questions those comparisons raise.
Some of the original report language is deliberately punchy. For implementation, I would use narrower language: a brand appeared frequently in this sample, a cited source was present, or a need-based question produced a different set of options. A snapshot cannot establish that a company permanently owns a category.
That restraint improves the recommendation. It lets me propose a testable next step instead of presenting an observation as a ranking factor.
A missing mention does not diagnose the model's knowledge
There is another inference I would avoid: “The brand did not appear, so the model does not know it.”
The Inside-Out research summarized by Google Research examines a distinction between internally encoded factual knowledge and what models express. Its case study uses open-weight models and closed-book factual questions. It is not a test of commercial shopping recommendations or these brands.
The relevance to my audit is caution about the inference, not a new explanation for the shelf. The paper cannot tell me that an absent brand was internally known, retrieved and rejected, or omitted for any particular reason.
My own studies observe answers and displayed sources. They do not expose model parameters. A brand's absence is a result to record; its hidden cause remains unresolved unless another method supplies evidence.
How I would investigate silence without inventing a mechanism
First, I would repeat the prompt under recorded conditions. A one-off absence and a recurring absence are different observations, although repetition alone still cannot expose internal knowledge.
Second, I would vary the wording while preserving the underlying need, documenting which constraints remain fixed. If I change price, location and audience together, I cannot attribute the difference to one of them.
Third, where the tool supports it, I would compare clearly labelled search-enabled and other available conditions. I would not assume the settings in one app reproduce the consumer product. Any comparison needs the actual configuration recorded.
Fourth, I would separate accurate characterization from recommendation. The system may describe the brand correctly when asked directly without including it in a need-based shortlist. That is useful evidence about output behaviour, not proof of why selection occurred.
Finally, I would compare the desired association with verifiable product facts and the available public descriptions. If the request is a poor fit, absence may be appropriate. If it is a credible fit but evidence is missing or unclear, that gives the business a concrete issue to investigate.
None of these steps promises to reveal a hidden ranking formula. They help keep “not named in this answer” from turning into “unknown to every model,” “penalized,” or “excluded because of one missing schema field.”
I would keep the test set small enough that a person can review the actual answers. The distinction between visibility, correct identity and appropriate selection is too important to outsource entirely to a single mention score.
The next question I would put beside the dashboard
After these studies, I would not stop at “Are we appearing?” I would ask: “For which decisions are we being considered, and does the evidence justify that association?”
That question creates a more useful conversation between SEO, product, content and operations. It can reveal that a brand needs clearer information, better evidence, a corrected description or a more realistic target.
Being recognized is one outcome. Being selected for an appropriate need is another. My AI Shelf studies made that difference visible enough to investigate.
Read the sustainable apparel study and skincare study for the original reports and their limits. For the wider framework that informed these questions, see Olaf Kopp’s work on brand context and AI visibility.